Modern data engineering is about more than moving data from one system to another. A production-ready data platform must be scalable, reliable, observable, easy to reprocess, and capable of supporting analytics and machine learning workloads.
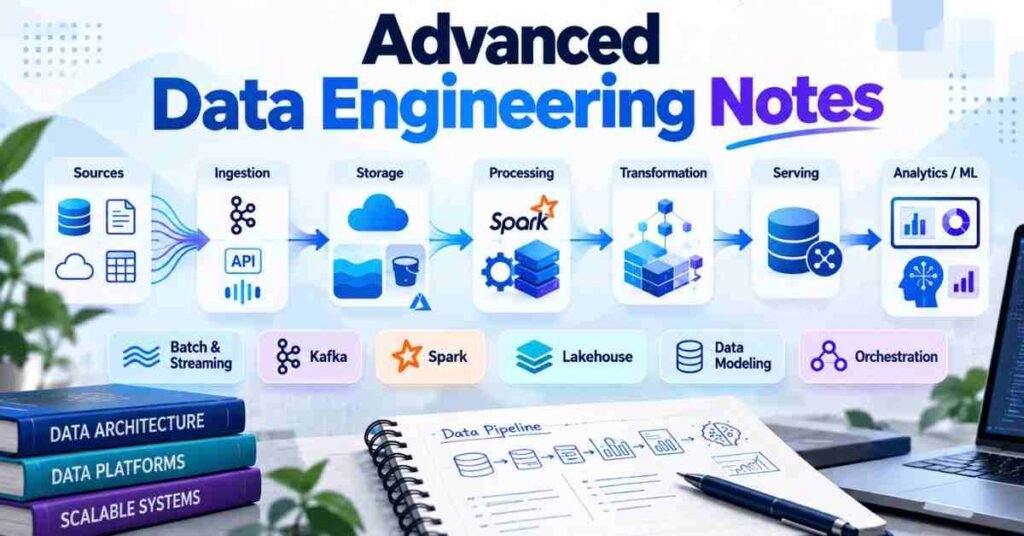
These Advanced Data Engineering Notes cover the complete flow from data sources → ingestion → storage → processing → transformation → serving → analytics or ML. The notes also introduce tools and concepts such as Kafka, Spark, dbt, Airflow, data lakes, warehouses, and lakehouse architectures. DATA ENGINEERING NOTES
The material also explains batch and streaming pipelines, Kafka architecture, Spark optimization, data modeling, CDC, orchestration, data quality, observability, cloud data engineering, and production workflow practices. DATA ENGINEERING NOTES
The Advanced Data Engineering Notes provide a structured view of how modern data systems are designed, built, optimized, and maintained.
From batch and streaming pipelines to Kafka, Spark, lakehouse architecture, CDC, workflow orchestration, data quality, observability, and cloud platforms, the notes focus on practical concepts used in production environments. DATA ENGINEERING NOTES DATA ENGINEERING NOTES
The final workflow also emphasizes senior-level practices such as designing for failure, preferring incremental processing, making pipelines idempotent, tracking lineage, securing sensitive data, monitoring cost and performance, planning backfills, and keeping pipelines easy to debug.